Logistics firms face substantial latency challenges due to rapid shipment updates; addressing eventual consistency is key to real-time visibility.
Understanding the Latency Dilemma
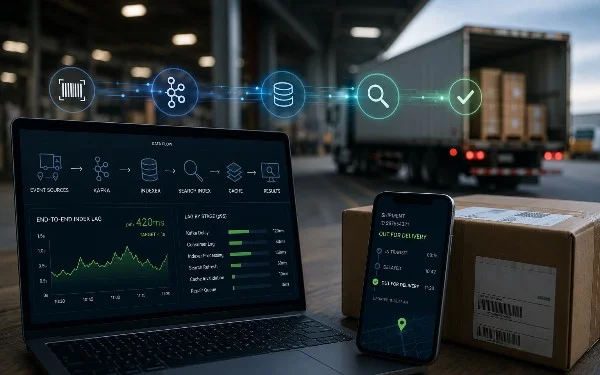
In the fast-paced world of logistics visibility, the state of a shipment can fluctuate thousands of times each second. Events such as package scans by carriers or route adjustments occur almost instantaneously, necessitating that these actions are rapidly processed and reflected in search indices. Kafka plays a pivotal role, capturing these events within milliseconds to ensure that operations stay current.
Latency isn’t just a buzzword in tech discussions; it’s a critical factor that affects supply chain efficiency. When a shipment is delayed or the status is stale, companies lose visibility into operations, which can lead to errors, dissatisfied customers, and financial losses. In a sector where every second counts, relying on outdated information is simply not an option. Hence, tools like Kafka are essential. They allow for the real-time handling of massive streams of data, ensuring that logistics firms can respond swiftly to shifts as they happen.
In practical terms, Kafka's role extends beyond simply capturing events. It organizes these events into a system that is not only scalable but also resilient. As logistics networks grow and become more complex, this architecture provides a framework that can handle the increasing volume of data without sacrificing performance. Yet, while Kafka can process this data quickly, the challenge lies in ensuring every layer of the tech stack can keep pace.
Confronting the Consistency Challenge
Historically, our engineering efforts to maintain precise, up-to-the-millisecond data updates struggled significantly. Despite our cluster appearing healthy and write operations being acknowledged, users experienced lag in search results. This phenomenon stems from what’s known as the eventual consistency problem. It's particularly deceptive; it doesn’t trigger alerts and often goes unnoticed until customers realize the data isn’t reflecting real-time truths.
The eventual consistency issue is a common challenge in distributed systems where multiple data copies exist. Unlike traditional databases that provide immediate consistency, distributed systems like those harnessing Kafka often operate under the assumption that eventual consistency will suffice. However, failure to communicate real-time updates can erode user trust. This isn’t merely a technical hiccup; it translates to real consequences in customer satisfaction. Users expect instantaneous information, and any delay damages the service’s credibility.
When many users search for shipment statuses, they rely on quick responses that reflect real-time updates. If they encounter lag or outdated information, it's likely they will seek alternatives. And yet, ensuring consistency across all layers of a tech stack is no small feat. From the database where the information is initially stored to the caching mechanisms that serve end-user requests, every element must work together seamlessly. This adds complexity, as inconsistency can occur at any point, and identifying the source of the delay becomes a daunting task.
Identifying Staleness Across the Stack
This consistency issue can arise at multiple points across the technology stack—from the replication quorum to the indexing engine, through to the cache tier and the background repair processes. Each layer contributes its own latency, complicating the system. Consequently, total end-to-end delay can exceed one second, even with all components appearing operational.
Understanding where staleness creeps in is critical for any organization seeking logistics efficiency. Start with the replication quorum, which is central to maintaining consistency. If not configured correctly, it can introduce significant delays in how quickly data is confirmed across different nodes. Then consider the indexing engine; it’s responsible for how quickly and accurately data can be retrieved during a query. If it’s not optimized, users may experience frustrating delays in search results.
The caching layer also plays an essential role. While it allows for rapid data retrieval, stale data can accumulate if the refresh policies aren’t stringent enough. Background repair processes, designed to fix inconsistencies across systems, can inadvertently create additional latencies if they’re poorly designed. Even if every component of the stack looks green and healthy, the reality can be starkly different. If you're working in this space, you'll understand the frustration of knowing the tech is technically functional, yet customer experiences prove otherwise.
Implications for the Logistics Industry
The implications of these latency and consistency challenges extend beyond technical details. For logistics companies, mitigating these issues can become a competitive differentiator. As customer expectations rise, the demand for real-time data has never been greater; businesses that cannot provide accurate and timely information may fall behind.
This brings to light an important factor: trust. Customers rely heavily on the information provided by logistics companies for planning purposes. When they can't trust that information, it undermines the entire relationship. Building a system that prioritizes real-time accuracy isn’t just a technical challenge; it’s a strategic imperative. Companies may need to invest in better monitoring systems that can proactively identify latency and performance issues before they impact users.
As logistics technology evolves and integrations with AI and machine learning systems ramp up, the focus on data visibility and accuracy will only intensify. Eventually, the industry's leading players will be those that can promise — and deliver — real-time insights with minimal latency. If this sounds ambitious, it reflects a necessary shift in approach. With technology racing ahead, it's time logistics firms caught up.



Discussion
Sign in to join the discussion.