Timely document updates are crucial for effective vector search systems; stale results can undermine overall performance despite other metrics appearing strong.
The Pitfall of Outdated Information
Vector search performance is typically evaluated through query latency, recall rates, and throughput. These metrics are commonly highlighted in technical assessments of such systems, yet they can often give a misleading picture if the underlying system retrieves outdated documents. A quick index may still deliver incorrect or irrelevant answers, which poses a significant concern for businesses relying on accurate data.
The Mechanics of Vector Search
To understand why outdated information can severely undermine the effectiveness of vector searches, it’s essential to grasp the mechanics involved. When a document is added to a database, that information is rarely available for immediate search. It has to traverse multiple stages, starting from event capture to the point where it can be indexed and retrieved. Each of these steps can introduce delays or errors, leading to discrepancies.
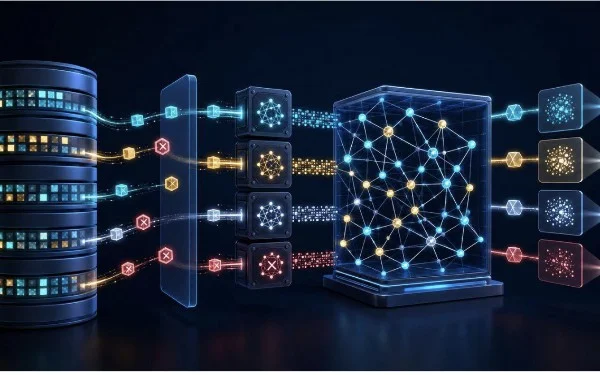
Consider the path from a database write to a searchable embedding. Initially, data is captured, often in real-time. Afterward, this information needs to be transported, which can introduce latency. Once transported, the data must be chunked—broken down into digestible pieces for embeddings. Here, the choice of chunking strategy may affect how well the information is represented in vector spaces.
This phase is followed by model inference, where machine learning algorithms interpret the data, generating embeddings that should represent the original content accurately in vector form. Subsequently, the index updates, which allow new queries to be answered based on the most recent data. Lastly, there’s cache invalidation—an often overlooked step. If caches aren’t updated promptly, even the newest data can remain inaccessible for user queries, resulting in outdated responses.
The Consequences of Delays
So, what happens when this intricate process falters? Organizations can end up making decisions based on stale or incomplete information. This is particularly detrimental in fast-paced industries like finance or healthcare, where timely data can make a difference between a successful initiative and a major setback. In these fields, relying on outdated information when billions of dollars or people’s lives are at stake becomes unacceptable.
And this is the part most people overlook: The focus on speed should not overshadow the need for accuracy. An effective vector search system doesn’t merely prioritize how fast it can produce search results; it must also ensure that those results are current and relevant. The trade-off between speed and accuracy isn’t just a technical choice; it reflects a company’s commitment to sound decision-making.
Industry Context: Similar Systems and Their Challenges
It might be useful to look at how other industries face similar issues with outdated information. For instance, in e-commerce, the freshness of product data plays a critical role in customer satisfaction and sales performance. If inventory isn’t updated in real-time, customers might find items they can’t purchase, leading to frustration and abandoned carts. Such issues stem from similar multi-step processes in data management; thus, the problem isn’t unique to vector search but is rather indicative of broader data integrity challenges.
Moreover, companies that rely on historical analytics often encounter these burdens too. If a system pulls data from a database that hasn’t been refreshed, users may draw conclusions that lead to misguided tactics. This failure to connect actions to current data not only hampers immediate operational efficiency but can also hurt long-term strategic planning.
Ensuring Data Freshness
Given the depth of this issue, how do companies ensure data freshness? One critical strategy involves implementing continuous updating mechanisms that reduce the time lag between data generation and index updates. Real-time data streaming can mitigate these delays, ensuring that search queries reflect the latest information available.
Another essential aspect is monitoring and fault-checking throughout the entire process of data handling—from capture to delivery. Establishing a feedback loop can help in identifying bottlenecks or failures that delay updates. Optimizing each step does mean a more substantive investment in technology and resources, but it’s one that can yield significant dividends in data reliability.
Future Outlook: What Lies Ahead?
As technology advances, one can anticipate improvements in both the efficiency and effectiveness of vector search systems. With the rise of machine learning, you’ll see increasingly sophisticated models that can handle more complex data accurately. These models could provide not just speed, but also a higher degree of accuracy in returning relevant results.
However, the looming challenge of keeping data fresh will remain. Real-time indexing techniques will have to evolve, especially as businesses increasingly depend on data-driven decisions. In what’s becoming a hyper-competitive environment, the ability to provide accurate and timely information isn’t a luxury—it’s a necessity.
What this means for you is that companies operating in data-intensive environments must not just focus on acquiring advanced vector search tools but should also pay keen attention to their underlying data management strategies. Outdated information won't just hinder the effectiveness of search systems; it can compromise the entire decision-making framework.



Discussion
Sign in to join the discussion.