YARN bills for allocated container memory, while executor placement can leave node cores unused. Allocation increments also affect how many executors fit.
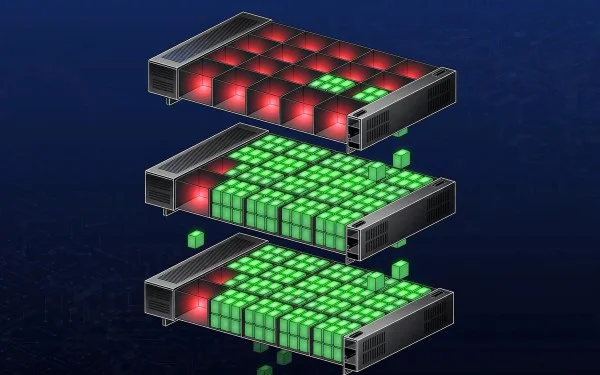
Executor packing can strand CPU capacity
A batch Spark job on YARN can consume nearly all its allocated memory while leaving half the CPUs idle. That apparent contradiction comes from how the two resources are measured and allocated: YARN reports memory reserved for containers, not memory actively used by the processes inside them, while the executors placed on a node may not fill its available cores. Since billing covers every vCPU, poor fit means paying for unused compute. The job can look memory-bound on a YARN dashboard even when its running executors aren't keeping the processors busy.
This is more significant than it looks. Cluster capacity is determined by what can be placed, not just by what a workload happens to use at a given moment. A container reserves a block of memory when it starts, and that reservation can prevent another executor from being scheduled even if the first executor's heap has plenty of free space. CPU capacity can be stranded in parallel: an executor layout may leave too few cores available for another container, or may request fewer executor cores than the node could support.
Memory and CPU therefore tell different parts of the story. YARN's reservation view helps explain why a node can't accept another container; actual process use helps explain whether the allocated memory is doing useful work. CPU utilization adds a third perspective. None alone is a complete measure of whether the job is sized well.
What determines an executor’s footprint
Spark requests one YARN container for each executor [3]. Its size combines the executor heap, configured with spark.executor.memory, and off-heap overhead from spark.executor.memoryOverhead. That overhead defaults to 10% of heap memory, with a 384 MiB floor [1]. The container request is consequently larger than the heap setting alone. Treating the heap value as the full memory cost understates what YARN must reserve for each executor.
The overhead allocation matters because an executor's process can need memory outside the Java heap. The heap holds objects managed by the Java runtime, while overhead covers other process needs; the precise use depends on the workload and configuration. If that allowance is too small, the container can run into memory trouble even when heap use looks acceptable. If it's larger than the process needs, more memory is reserved per executor, which can reduce how many containers fit on a node.
Within the heap, Spark reserves a small area, then assigns 60% of usable memory by default to a unified pool for execution and storage. The spark.memory.fraction setting controls that share; the remaining heap serves user data structures [2]. Execution and storage draw from a shared pool, so the division isn't simply a fixed split between computation and cached data. The setting describes how much heap is available to those Spark-managed tasks, not how much memory YARN reserves for the container.
YARN rounds container requests to its allocation increment, so actual executor placement can differ from estimates based on raw sizes [4]. Sizing needs to account for that rounding as well as the node’s core count. A request just above an allocation boundary may consume the next increment, changing how many executors fit even though the configured increase looks small. The result is a packing problem: memory requests, rounding rules, and executor core counts all constrain placement.
Why memory fit doesn't guarantee CPU fit
Consider a node with enough memory for another executor but too few available cores for the executor's configured core request. YARN can't place that container there, so some memory may remain unused. The reverse can happen too: there may be cores available, but the remaining memory is smaller than the next rounded container request. In either case, the node's total capacity doesn't translate cleanly into usable capacity for this particular executor shape.
This is why comparing a cluster's total vCPUs with its total memory can mislead. Executors arrive as paired requests for memory and cores. The proportions in those requests need to line up reasonably well with the nodes that run them. A workload with large containers may fit only a small number of executors per node; one with smaller containers may pack more flexibly, depending on the configured core count and YARN's allocation increment.
Here's the thing: a job can be inefficient even when each individual setting looks defensible. Heap sizing may reflect the data processed, and overhead may follow Spark's default, but their combined container size can still create awkward gaps on the node. Those gaps are a consequence of discrete allocations. Resources come in whole containers, not in perfectly divisible slices.
Reading the signals and tuning the fit
Diagnosing the mismatch calls for comparing configured requests with placement and usage. YARN's reserved-memory figures show the container footprint; process or executor metrics help show actual memory use; CPU metrics indicate whether allocated cores are doing work. If those views disagree, the difference is useful evidence. It may point to oversized reservations, limited parallelism, placement constraints, or simply a workload that doesn't keep its executors busy throughout the run.
Changing heap size alone can shift several constraints at once. A smaller heap can reduce the container request, but it also reduces the space available to Spark's unified pool and user data structures. Raising executor cores can make better use of a node's CPUs in some configurations, yet it also changes each executor's parallel work and may alter how many containers fit. There isn't a single setting that improves both memory and CPU fit for every job.
If you're working in this space, assess the executor as a whole: heap, overhead, core count, YARN rounding, and the node's available resources. Then compare that planned shape with what the scheduler actually places. The aim is to find a configuration that supports the workload while leaving fewer unusable fragments of capacity. (And this is the part most people overlook.)
Implications for cluster efficiency
For teams paying by vCPU, idle cores have a direct cost even when memory reservations make the cluster appear busy. Better packing can improve the amount of useful work obtained from allocated capacity, but the metrics don't promise that a configuration change will reduce runtime or cost: the workload's behavior and the scheduler's placement both matter. A more balanced resource shape is a practical starting point, not a guarantee.
That said, the mismatch is a reminder that utilization is not one number. Reserved memory, used memory, and CPU activity answer different questions, and a healthy reading in one can hide waste in another. The useful question is whether the executor layout matches both the job's needs and the node's shape. Sometimes the answer is a configuration adjustment. Sometimes it's simply a workload that has more memory demand than parallel work at that moment. Fewer stranded resources. Better evidence for the next sizing decision.



Discussion
Sign in to join the discussion.